Contact Us

Blog
October 15, 2026
Graid Technology Featured in TechArena’s AI Infrastructure Report, The Integrated Machine
TechArena has published The Integrated Machine, a new report on how rack-scale integration is changing the economics of AI infrastructure. TechArena’s editorial team spent the summer interviewing more than 20 companies across the AI infrastructure stack, covering compute, memory, networking, power, cooling, and firmware. Graid Technology was one of them. Field CTO Randy Kreiser contributed to the report’s sections on storage, memory, and rack-scale design.
The report argues that AI infrastructure is now measured by the cost and quality of the tokens it produces. Operators who run their infrastructure as one integrated system can predict that cost with much more confidence than operators who assemble it from separate parts.
Inference Is a Memory Problem
Kreiser explained how inference changes the constraint. Training is limited by how quickly data can be processed. Inference is limited by how much conversational state the system can keep available. Every active request carries a KV cache, the model’s working memory for a conversation. That cache grows with context length and with the number of concurrent users. Agentic workloads make it worse because a long-running agent keeps adding state at every step.
Moving KV cache to NVMe storage can extend the memory available for inference, but only when the storage path is fast enough. “Fetch must beat recompute. If it does not, the offload tier works against you,” Kreiser said.
The Benchmark
The report includes results from a controlled vLLM and LMCache test. The test ran a 235 billion parameter mixture-of-experts model on four NVIDIA H200 GPUs:
- No offload: 29.4 seconds time to first token (TTFT)
- Conventional Linux software RAID: 36.6 seconds TTFT
- Graid Technology’s GPU Accelerated Storage approach: 9.0 seconds TTFT, 3.27 times faster than no offload
The software RAID result shows Kreiser’s point in practice. Adding data protection to a storage path that is too slow made inference slower.
Storage Designed for the Rack
Kreiser also discussed what rack-scale deployment means for storage. Once the rack becomes the unit of deployment, storage has to be designed in from the beginning rather than integrated afterward. Over the next two years, he expects buyers to judge storage by inference outcomes such as cost per million tokens served, cache-hit rate, and time to first token. Capacity will still matter, but it will no longer be the main metric.
Read the Full Report
The Integrated Machine follows a single constraint up the AI infrastructure stack, from the chip through memory, networking, optics, power, cooling, and the control plane.
Read the full TechArena report: https://techarena.ai/content/techarena-report-the-integrated-machine
News & Resources
Visit Graid Technology at SC26 Booth 1326 in Chicago, November 17–19, to see GPU-accelerated I/O for AI inference and CPU-native data protection with VROC™ by Graid Technology. Stop by to enter our raffle for a pair of Meta glasses.
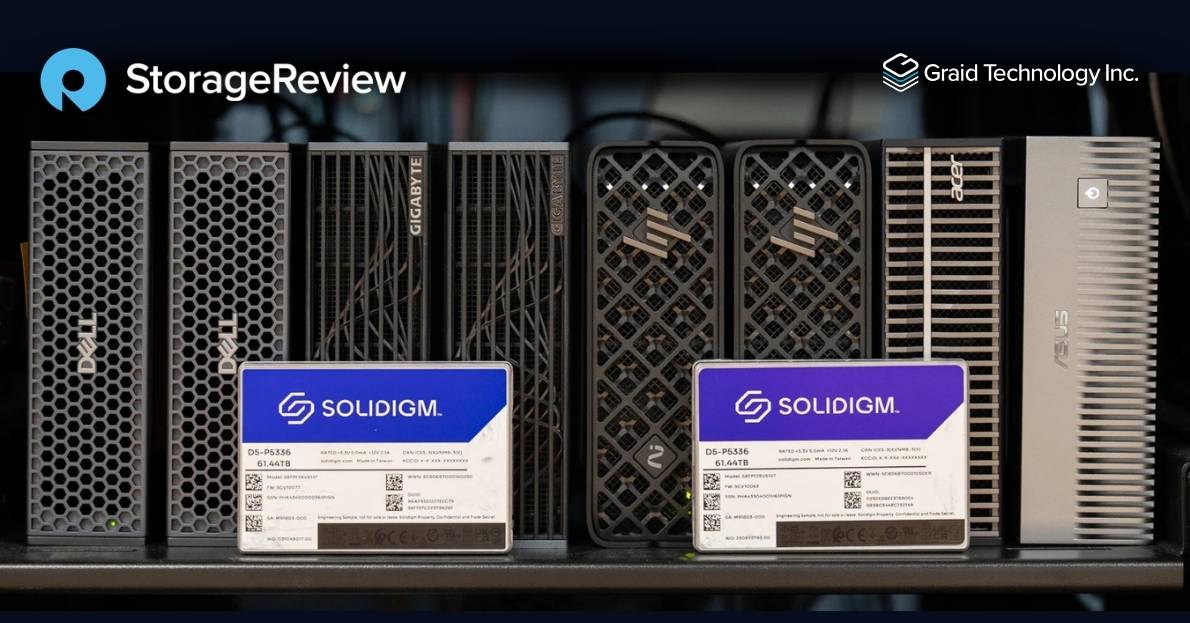
Storage Review built a shared storage host that gives eight NVIDIA DGX Spark systems access to one parity-protected Solidigm QLC pool, with SupremeRAID™ handling RAID 5 on a GPU. Here is what the testing showed and why it matters for AI labs and enterprise desktop AI fleets.
October 15, 2026
Graid Technology Featured in TechArena’s AI Infrastructure Report, The Integrated Machine
Graid Technology is featured in TechArena’s report The Integrated Machine. Field CTO Randy Kreiser discusses KV cache, inference performance, and why storage has to be designed into the rack from the start.