Contact Us
Podcast
September 14, 2026
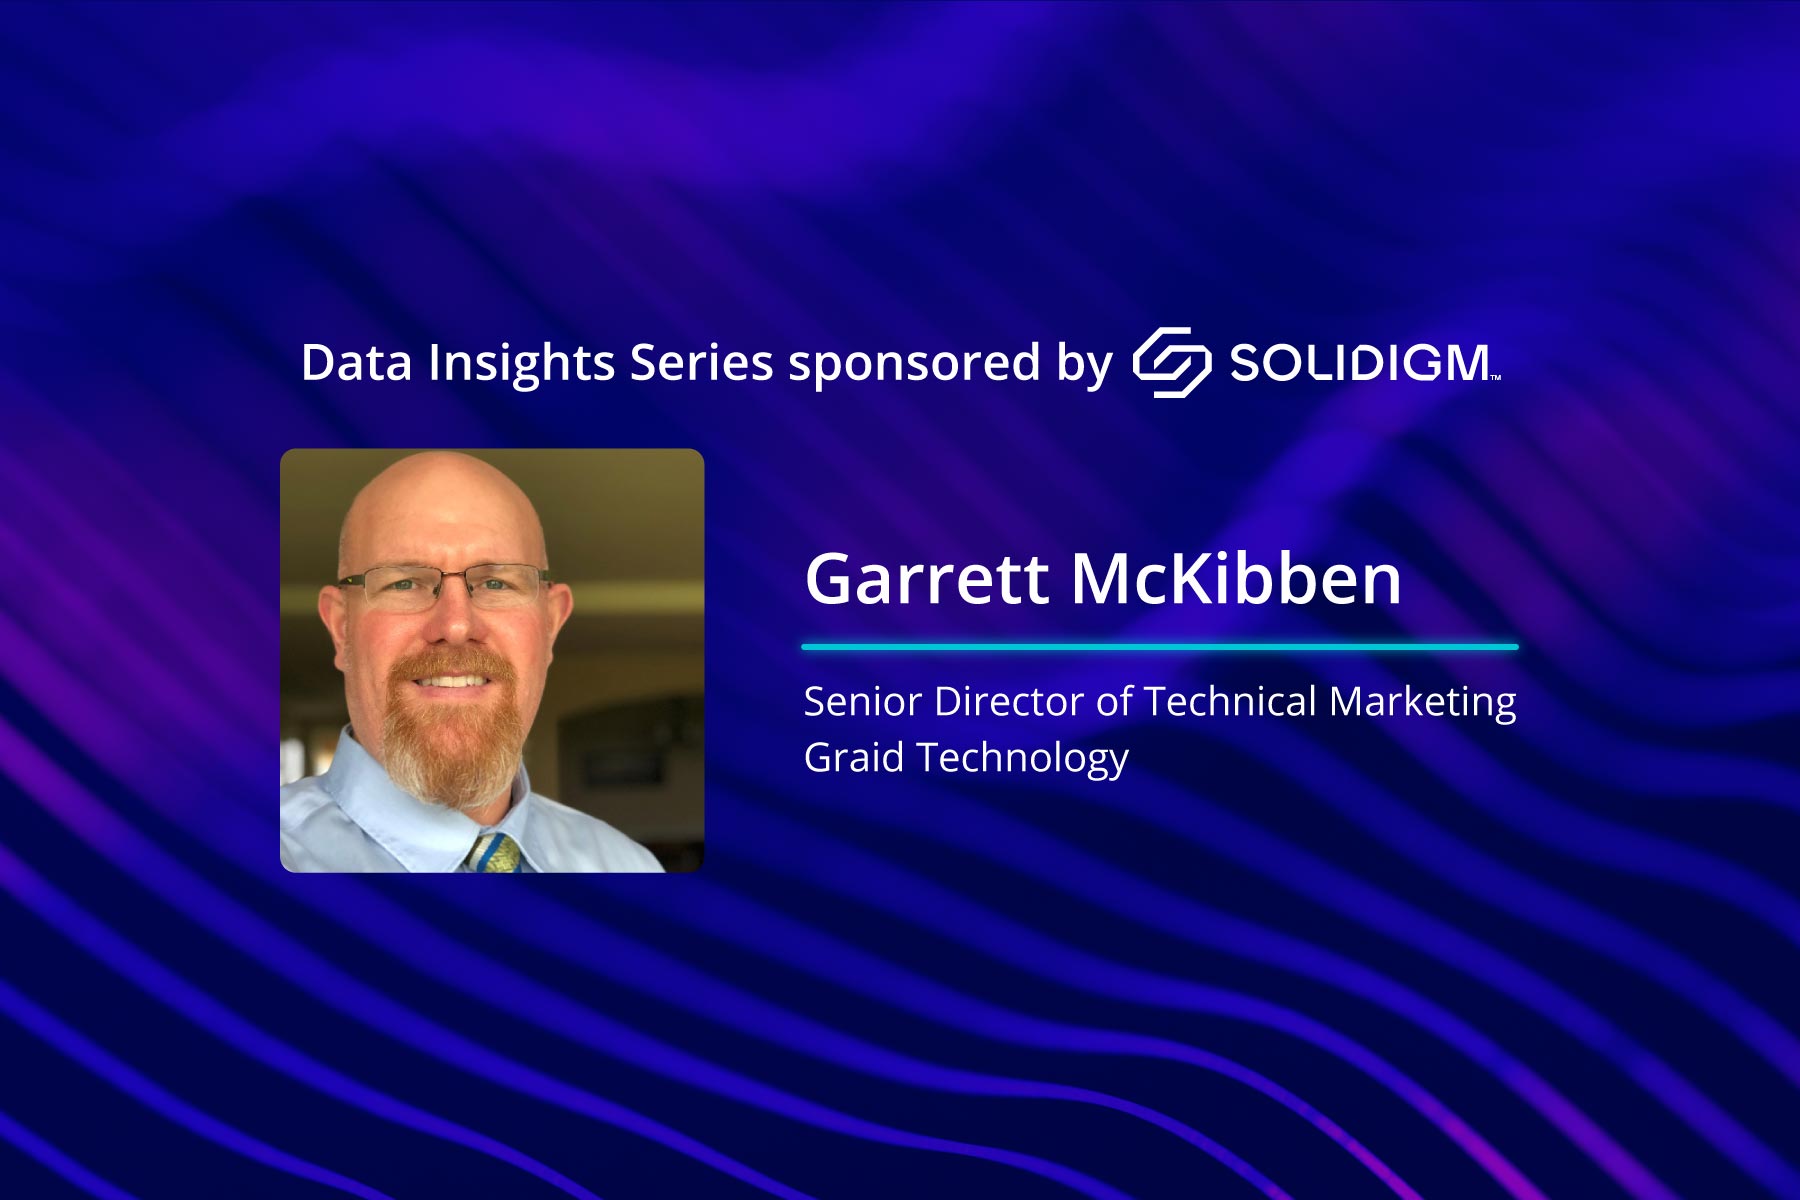
Breaking the KV Cache Inference Wall — Solidigm Data Insights Podcast, Featuring Graid Technology
"You've got a four-lane highway, and to get to your storage, you have to go down to a one-lane bridge."
That's how Garrett McKibben, Senior Director of Technical Marketing at Graid Technology, described the storage bottleneck choking modern AI infrastructure on the latest episode of TechArena's "Data Insights" podcast with Allyson Klein and Jeniece Wnorowski (Solidigm).
The Real Bottleneck
The conversation centered on KV cache, the working memory an inference model holds for every active request. Demand for that memory grows with context length and the number of concurrent users, and teams run out of room fast. McKibben put hard math on it: a Blackwell GPU tops out near 180 gigabytes of HBM at $50 to $80 per gig, and concurrency collapses after three or four users. Buying another Blackwell for every few users just doesn't pencil out.
Moving the Overflow to NVMe
Graid Technology's answer moves that overflow to an NVMe tier and accelerates the IO path on the GPU itself, using roughly 4% of the GPU before releasing those resources back. The company has published testing measuring time to first token when KV cache overflowed to fast storage instead of being recomputed, and in long-context runs, fetching beat recompute.
What's Next
The discussion also covered rack-scale design, agentic workloads that run for hours at a time, and what a team should actually measure to know whether its storage is pulling its weight.
Watch the full episode above.
Learn more about SupremeRAID™ and VROC™ by Graid Technology at graidtech.com.
News & Resources
Visit Graid Technology at SC26 Booth 1326 in Chicago, November 17–19, to see GPU-accelerated I/O for AI inference and CPU-native data protection with VROC™ by Graid Technology. Stop by to enter our raffle for a pair of Meta glasses.
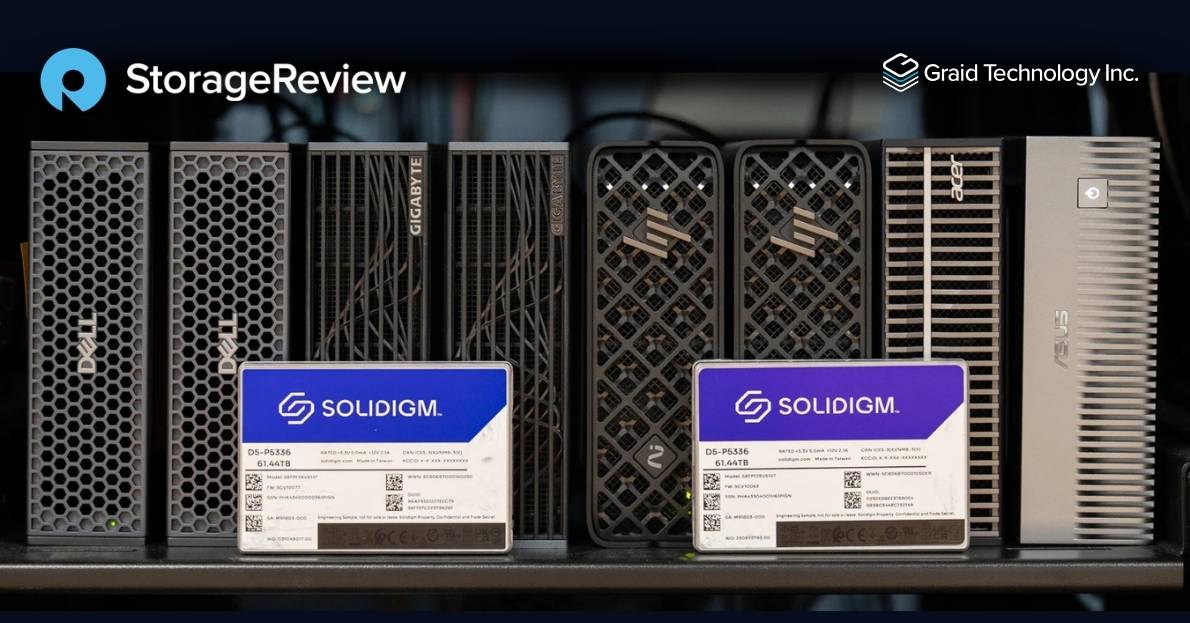
Storage Review built a shared storage host that gives eight NVIDIA DGX Spark systems access to one parity-protected Solidigm QLC pool, with SupremeRAID™ handling RAID 5 on a GPU. Here is what the testing showed and why it matters for AI labs and enterprise desktop AI fleets.
October 15, 2026
Graid Technology Featured in TechArena’s AI Infrastructure Report, The Integrated Machine
Graid Technology is featured in TechArena’s report The Integrated Machine. Field CTO Randy Kreiser discusses KV cache, inference performance, and why storage has to be designed into the rack from the start.