Get the SupremeRAID™ Summer 6-Pack! Buy 5 licenses, get the 6th FREE / Read the Storage Tax Blog
Contact Us

Video
March 11, 2026
Storage Is the AI Bottleneck. Here's What to Do About It.
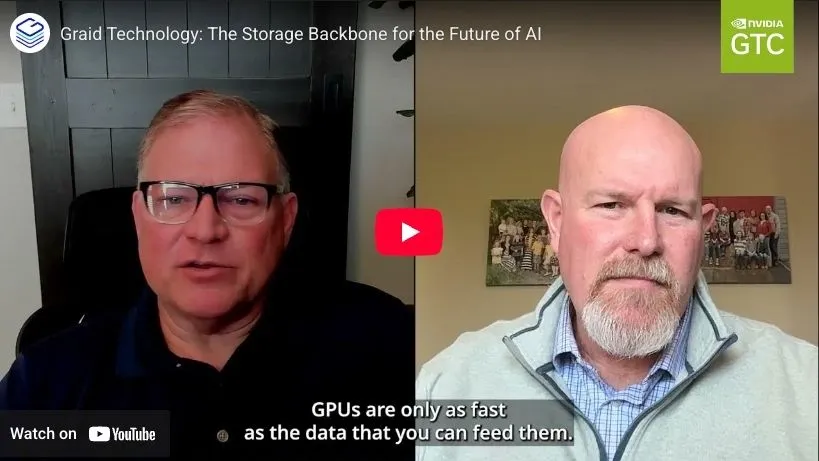
Your GPUs are only as fast as the data you can feed them.
There's a persistent misconception in AI infrastructure: that inference is stateless. It isn't. Every large language model processing long-context conversations generates KV cache data that has to live somewhere. When GPU memory fills up, that data spills directly to NVMe storage. If your storage can't keep pace, your model slows down. It's that direct. This is the bottleneck most infrastructure teams aren't talking about — and it's exactly what Graid Technology is solving.
Our SupremeRAID™ solution offloads RAID processing from the CPU to the GPU, delivering:
— Tens of millions of IOPS
— Hundreds of GB/s throughput
— Full enterprise resilience
— without taxing your compute
The result is higher GPU utilization, lower cost per token, and KV cache overflow that hits NVMe at near in-memory speeds.
Watch here as Garrett McKibben and Kelley Osburn break it all down in our latest video. If you're building or evaluating AI infrastructure, this one is worth your time!
And if you're attending NVIDIA GTC next week — come find us. We'll be at Booth 112. Let's talk storage!
News & Resources
Graid Technology will showcase SupremeRAID™ AE and Supreme JBOF at Cypher 2026 in Bengaluru, October 7–9. Explore GPU-accelerated NVMe storage and protected KV cache offloading for AI workloads from server to edge.
September 14, 2026
Breaking the KV Cache Inference Wall — Solidigm Data Insights Podcast, Featuring Graid Technology
"You've got a four-lane highway, and to get to your storage, you have to go down to a one-lane bridge." Garrett McKibben joins Solidigm on TechArena's Data Insights podcast to unpack why KV cache overflow is choking AI inference.
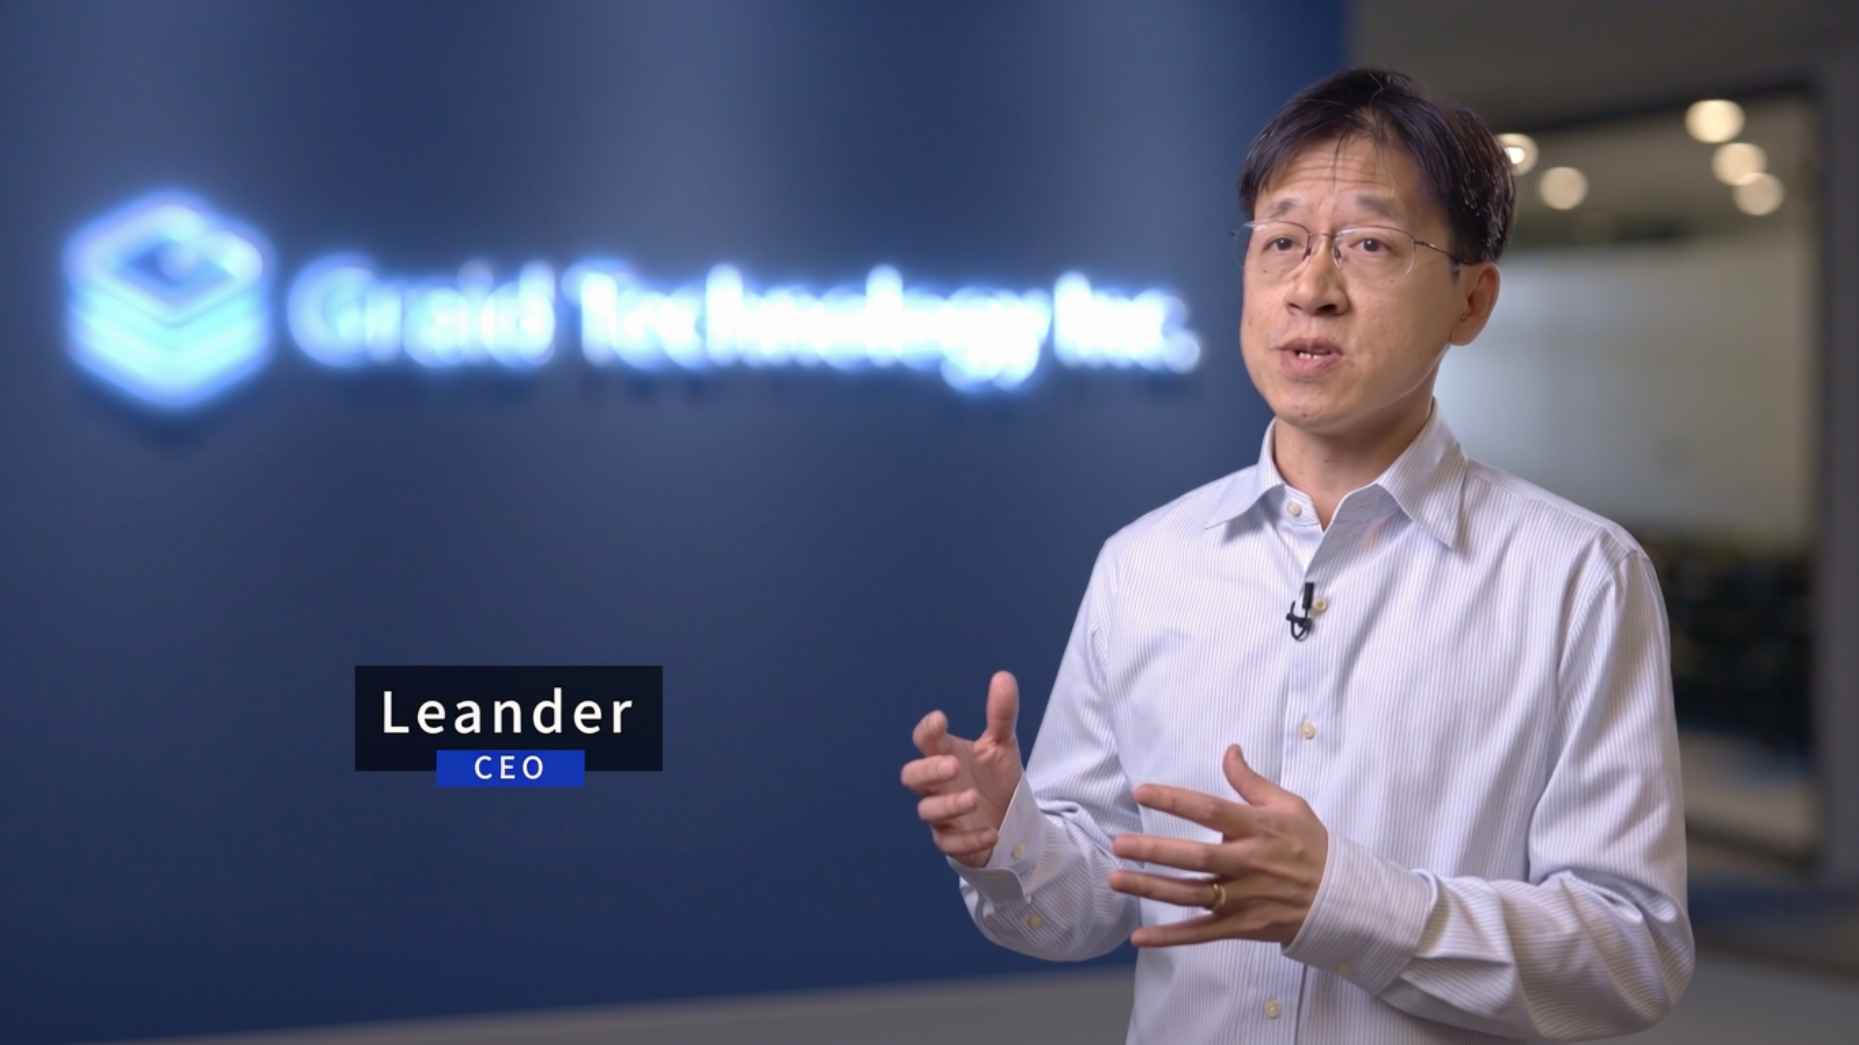
Graid Technology CEO Leander Yu and VP of Product Development Alven Yen explain how moving RAID processing onto the GPU breaks the bottleneck traditional controllers cannot solve, delivering 36 million GPU-initiated IOPS for AI infrastructure.