Contact Us


Events
May 26, 2026
Join Us at Interop Japan 2026
As AI models continue to scale, GPU memory and storage performance are becoming critical challenges in modern inference infrastructure.
KV cache offload to NVMe is no longer optional for many production AI environments — but without the right storage architecture, it can introduce additional latency, bottlenecks, and performance instability.
That’s where SupremeRAID™ AE and SupremeRAID™ HE come in.
SupremeRAID™ AE is designed for AI and GPU servers, enabling high-performance KV cache offload to local NVMe with near-native NVMe performance and enterprise-grade data protection.
SupremeRAID™ HE extends this performance to AI data centers and HPC clusters, delivering high-availability RAID for shared NVMe storage environments while supporting scalable, resilient infrastructure for large-scale AI workloads.
Together, SupremeRAID™ AE and HE help AI infrastructure overcome storage bottlenecks — from single GPU servers to rack-scale AI deployments.
At Interop Japan(株)ナノオプト・メディア 2026, we’re excited to showcase how Graid Technology enables high-performance, highly reliable AI storage for the next generation of inference infrastructure. See you in Tokyo! 🇯🇵🚀
📍 Booth 5U12-5 | June 10-12 | MAKUHARI MESSE, Tokyo
News & Resources
October 15, 2026
Graid Technology Featured in TechArena’s AI Infrastructure Report, The Integrated Machine
Graid Technology is featured in TechArena’s report The Integrated Machine. Field CTO Randy Kreiser discusses KV cache, inference performance, and why storage has to be designed into the rack from the start.
September 14, 2026
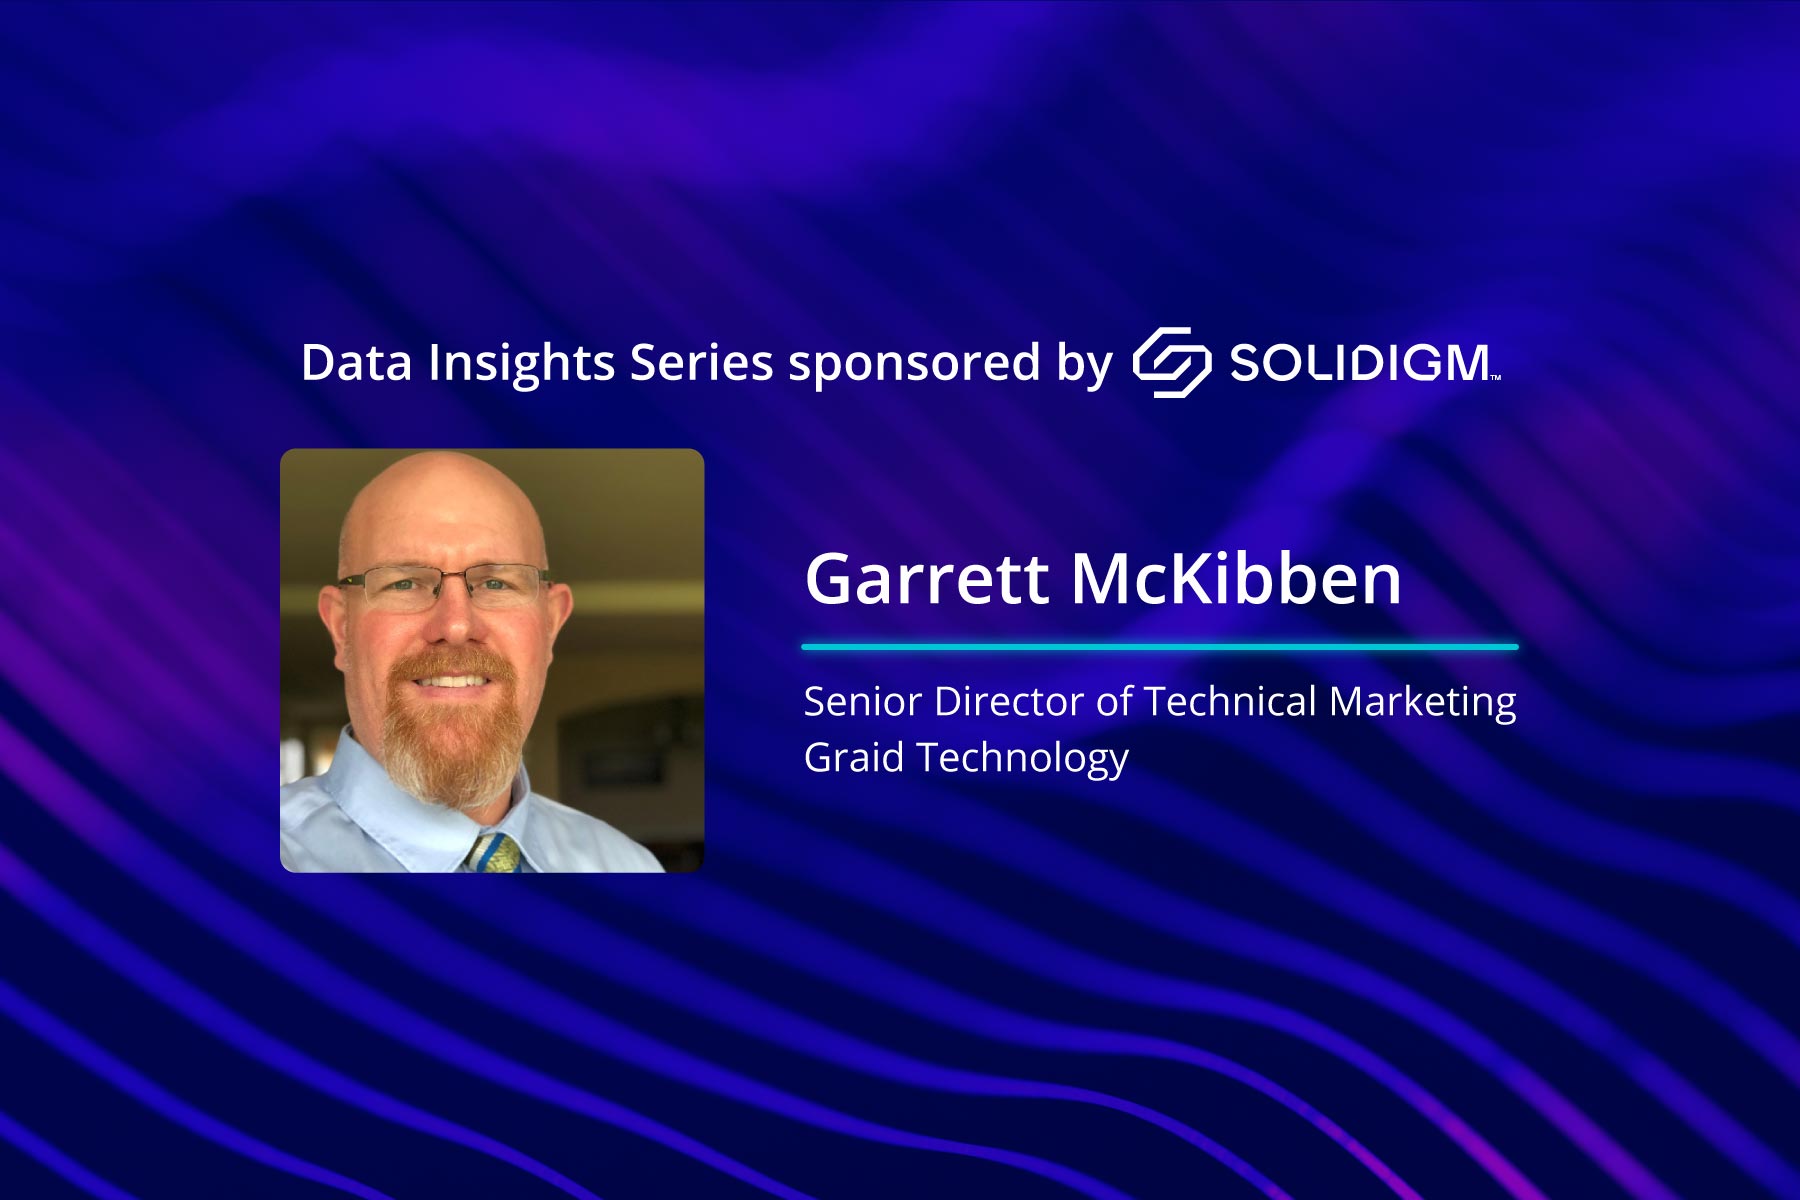
Breaking the KV Cache Inference Wall — Solidigm Data Insights Podcast, Featuring Graid Technology
"You've got a four-lane highway, and to get to your storage, you have to go down to a one-lane bridge." Garrett McKibben joins Solidigm on TechArena's Data Insights podcast to unpack why KV cache overflow is choking AI inference.
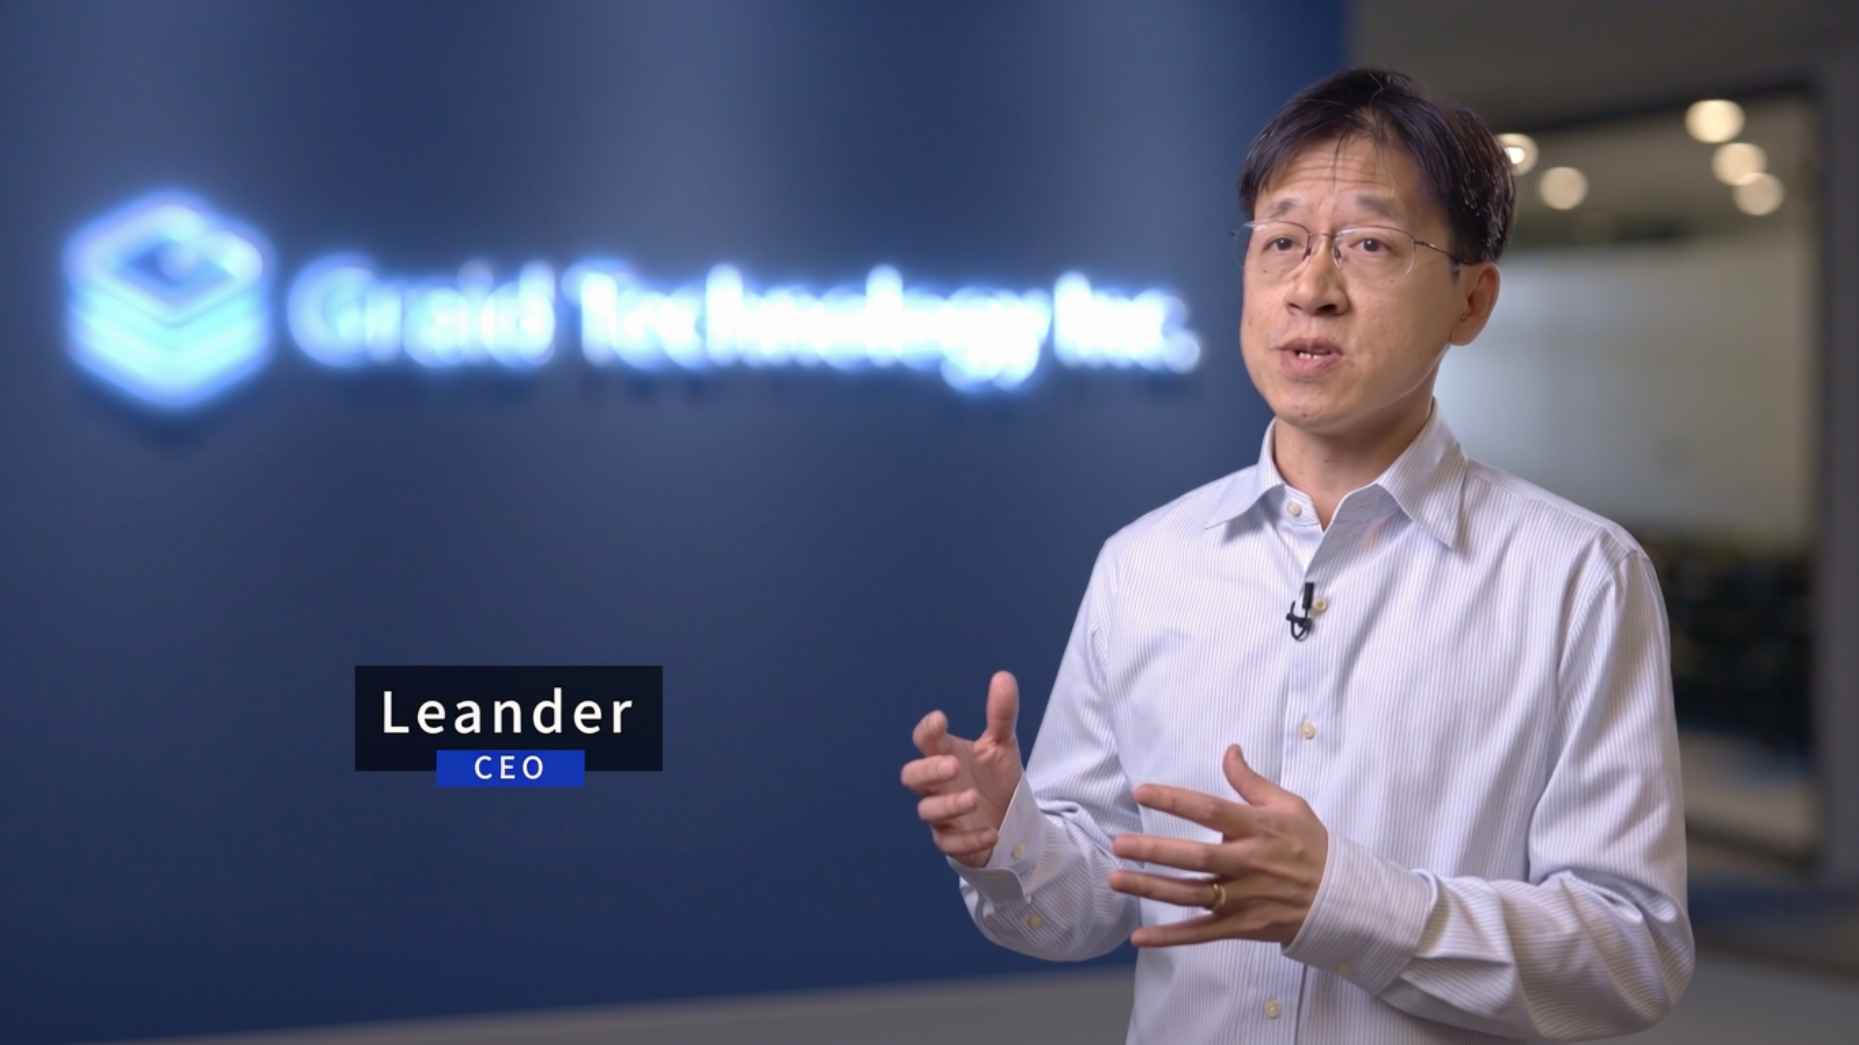
Graid Technology CEO Leander Yu and VP of Product Development Alven Yen explain how moving RAID processing onto the GPU breaks the bottleneck traditional controllers cannot solve, delivering 36 million GPU-initiated IOPS for AI infrastructure.